0 · Recall Warm-up
Answer from memory first. Answers are in the Answer Vault at the end of this lesson.
- In
sum = sum + 1;, how many tokens are there and issuma lexeme or a token name? from Lesson 1.1.1 - Simulate the DFA for “ends in ab” (states {p}, {p,q}, {p,r}) on
aab. Does it accept? from Lesson 0.2.3 - Which tool replaces
#define N 10uses of N by 10? from Lesson 0.1.2
1 · The Story
📖
The invoice
Translation House bills clients per stamp. Mrs. Desai asks Mira to count the stamps in a passage before the invoice goes out, and gives her the house rules.
A quotation inside the speech, however long, gets one QUOTE stamp. Margin notes are not stamped at all. Every punctuation mark gets its own stamp. And when two marks are written together as one symbol, like the Gujarati double danda, Mira takes the longest symbol she can and stamps it once.
A client complains: “You billed ++ as one stamp but + + as two!” Mira explains: “Glued together it is one symbol; with a space, two.”
2 · Predict First
🤔
How many tokens are in printf("i = %d, &i = %x", i, &i);?
Write your guess down. The answer is in the vault.
3 · Core Concept
The counting rules
- Whitespace (blanks, tabs, newlines) produces no token.
- Comments (
/* … */and// …to end of line) produce no token. - A string literal
"…"is exactly one token, whatever is inside (format specifiers, commas, even/*). - A character constant
'a'or'\n'is one token. - Every keyword, identifier and number (including
3.14and2.5e3) is one token. - Every punctuation mark is one token: ( ) { } [ ] ; ,
- Every operator is one token, and multi-character operators count once: ++ -- += -= *= /= == != <= >= && || -> << >> <<= …
Longest match
When characters could form a short or a long operator, the lexer always takes the longest match (also called maximal munch). It reads greedily from left to right and never looks at what the parser would prefer:
| Source | Tokens | Count |
|---|---|---|
x+++y | x ++ + y | 4 |
a---b | a -- - b | 4 |
i+++++j | i ++ ++ + j | 5 (then a syntax error) |
x+ ++y | x + ++ y | 4 |
A space stops the munch: x+ ++y becomes x, +, ++, y.
Comments inside literals and literals inside comments
"/* not a comment */"is one string literal: inside quotes,/*is ordinary text.// see "file"is all comment: inside a comment, quotes are ordinary text.- C block comments do not nest:
/* a /* b */ c */ends at the first*/, leavingc */as code.
A worked count on one program
int main() {
  /* find max */
  int x = 5, y = 7;
  if (x >= y) printf("%d", x);  // print
  else y += x++;
  return 0;
}
Count per line: line 1 gives 5 (int main ( ) {); the comment line gives 0; line 3 gives 9; line 4 gives 13 (if ( x >= y ) printf ( "%d" , x ) ;); line 5 gives 6 (else y += x ++ ;); line 6 gives 3; line 7 gives 1. Total 37.
Story → compiler term
| In the story | In the compiler |
|---|---|
| one stamp per word or mark | one token per lexeme |
| a whole quotation = one QUOTE stamp | a string literal is one token |
| margin notes are not stamped | comments produce no tokens |
| spaces are not stamped | whitespace produces no tokens |
| two marks written together = one symbol | multi-character operators (++, >=) are one token |
| take the longest symbol you can | longest match (maximal munch) |
| “+ +” with a space = two stamps | whitespace separates lexemes |
4 · Visual
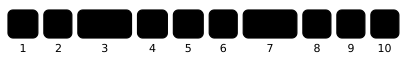
The classic: 10 tokens in printf("i = %d, &i = %x", i, &i);

Multi-character operators are single tokens: += and ++.
5 · Worked Examples
Example 1 Easy
Count the tokens in int a = 10, b = 20;.
Solution
int a = 10 , b = 20 ; = 9. Each comma is a punctuation token; each 10 and 20 is one number.
Example 2 Medium
Count the tokens in printf("i = %d, &i = %x", i, &i);.
Solution
printf · ( · "i = %d, &i = %x" · , · i · , · & · i · ) · ; = 10. The format string is one QUOTE stamp; the & outside the quotes is a real operator token.
Example 3 GATE
Count the tokens in the program shown in the core concept (with the comment line and the // comment).
Solution
Comments vanish, the string "%d" is one token, >=, += and ++ are single tokens. Total 37, counted line by line above and confirmed by running a C tokenizer.
6 · Shortcuts
⚡
Count by lines, skip comments first, then box every string literal as one token, then split operators greedily. Valid when: any “count the tokens” question in C.
⚡
Longest match: from left to right take the longest operator that fits; never re-split to please the grammar. Valid when: runs of + - < > = & | characters such as x+++y.
7 · GATE Traps
⚠️
- Everything inside quotes is one token, including
%d,\n, commas and/*. &in&ioutside the string is a separate token.x+++yis x ++ + y (4 tokens), not x + ++ y.- Comments do not nest in C.
- A number like
2.5e3is one token, not 2, ., 5, e, 3. mainandprintfcount as identifiers (still one token each).
8 · Memory Hook
🧠
“Quotes are one, comments are none, operators munch.”
9 · Connect the Dots
Counting tokens needs only the rules. Building a lexer needs a precise pattern for each token kind. The next lesson writes those patterns as regular definitions, reusing Primer 0.2.2.
10 · Self-Test
GATE format. Try every question before opening the vault.
Q1NAT1 markToken count
How many tokens are in while (i = 10) i++;?
Numerical answer: ________
Q2NAT1 markLongest match
How many tokens are in a = b+++c;?
Numerical answer: ________
Q3NAT1 markString literal
How many tokens are in char *s = "/* not a comment */"; // done?
Numerical answer: ________
Q4MCQ1 markLongest match
The lexer splits a---b as:
- (A) a, -, --, b
- (B) a, --, -, b
- (C) a, -, -, -, b
- (D) a, ---, b
Q5NAT2 marksToken count
How many tokens are in for (i = 0; i n; i++) sum += a[i]; /* add */?
Numerical answer: ________
11 · Rule Card
- Whitespace, comments → 0 tokens.
- String literal, character constant → 1 token each, whatever is inside.
- Keyword, identifier, number (3.14, 2.5e3) → 1 each.
- Each punctuation mark and each operator → 1; multi-character operators (++, >=, +=, ->, =) count once.
- Longest match from the left: x+++y = x ++ + y.
- C comments do not nest; quotes inside comments and /* inside quotes are plain text.
12 · Concept Ledger
longest match (maximal munch)character constantmulti-character operatorcomment (block, line)whitespace
13 · Answer Vault
Answer Vault
Try the questions first. Open when you are ready to check.
Warm-up
- 6 tokens;
sumis a lexeme (its token name is id). - {p} –a→ {p,q} –a→ {p,q} –b→ {p,r}: accept.
- The preprocessor.
Predict First
10: printf ( "i = %d, &i = %x" , i , & i ) ;. Everything between the quotes is one string literal token, including the comma, = and %d inside it.
Self-Test
Q1 Answer: 91 mark
while · ( · i · = · 10 · ) · i · ++ · ; = 9.
Re-read: Lesson 1.1.2 — Counting tokens in C code: whitespace, comments, string literals, ++ and >=
Q2 Answer: 71 mark
Longest match gives a · = · b · ++ · + · c · ; = 7.
Re-read: Lesson 1.1.2 — Counting tokens in C code: whitespace, comments, string literals, ++ and >=
Q3 Answer: 61 mark
char · * · s · = · the string literal · ; — the /* … */ inside quotes is text, and // done is a comment: 6.
Re-read: Lesson 1.1.2 — Counting tokens in C code: whitespace, comments, string literals, ++ and >=
Q4 Answer: (B)1 mark
Longest match from the left: -- first, then -.
- (A) is wrong: The lexer takes the longest operator first, not the shortest.
- (C) is wrong: That ignores the -- operator.
- (D) is wrong: C has no --- operator.
Re-read: Lesson 1.1.2 — Counting tokens in C code: whitespace, comments, string literals, ++ and >=
Q5 Answer: 202 marks
for · ( · i · = · 0 · ; · i · · n · ; · i · ++ · ) · sum · += · a · [ · i · ] · ; = 20; the comment adds none.
Re-read: Lesson 1.1.2 — Counting tokens in C code: whitespace, comments, string literals, ++ and >=