0 · Recall Warm-up
Answer from memory first. Answers are in the Answer Vault at the end of this lesson.
- Give the preorder of a tree whose root R has children A (with child C) and B. from Lesson 0.2.4
- Which strings does the regular expression
[0-9]+describe, and does it include ε? from Lesson 0.2.2 - What is the difference between a compiler and an interpreter? from Lesson 0.1.1
1 · The Story
📖
A morning at the Word Desk
Kabir at the Sentence Desk never reads raw letters. Whenever he is ready for more, he rings a bell and says: “Next word, please.”
Mira, at the Word Desk, then reads letters from the speech until she has cut out one complete word. The exact letters she cut, for example Ramesh, are what she cut. She checks it against her pattern cards (“capital letter then small letters”), finds which card it fits, and stamps the word with that card’s kind: NAME.
A stamp alone loses information: two different names would look identical to Kabir. So for names Mira also writes a page number from the Index Book on the stamp: NAME, page 12, and on page 12 she records everything known about Ramesh. For amounts she writes the value: AMOUNT, 50.
Spaces, line breaks and the speaker’s pencil notes in the margin never become stamps; Mira skips them. She does keep count of the lines, so that a complaint can say “line 7”.
2 · Predict First
🤔
In the C statement if (count >= 10) count = 0;, the name count appears twice. Does the lexer produce one token for it or two?
Write your guess down. The answer is in the vault.
3 · Core Concept
Three words that are easy to mix up
| Term | Meaning | Example |
|---|---|---|
| Lexeme | the actual sequence of characters in the source that forms one unit | count, >=, 10 |
| Token | a pair ⟨token name, attribute value⟩; the token name is the kind of unit | ⟨id, →count⟩, ⟨relop, GE⟩, ⟨num, 10⟩ |
| Pattern | the rule describing all lexemes of one token name, usually a regular expression | id → letter (letter |
Many lexemes can share one pattern (count, x, total are all ids). Each lexeme in the source produces its own token.
Token classes in C-like languages
- Keywords: if, else, while, int, return, … (one token name per keyword, or one name “keyword” with the word as attribute).
- Identifiers: names of variables and functions (main and printf are identifiers, not keywords).
- Constants: integer and floating numbers, character constants like
'a'. - String literals:
"hello %d", one token including the quotes. - Operators: + ++ += <= == && -> …
- Punctuation: ( ) { } [ ] ; ,
Whitespace and comments are not tokens; the lexer removes them.
Attributes
The parser decides structure using token names only; later phases need more. The attribute carries that extra information:
- for an identifier: a pointer to its symbol table entry (lexeme, type, location, …);
- for a number: its value;
- for a relational operator: which one (LT, LE, EQ, …).
How the lexer and parser cooperate
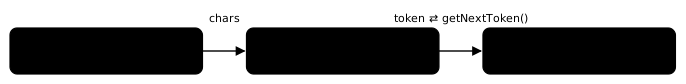
The parser is the boss. It calls getNextToken(); the lexer reads characters until it has one lexeme, enters identifiers into the symbol table (or finds the existing entry), and returns the token. The lexer is therefore usually a subroutine of the parser, not a separate pass.
Along the way the lexer also strips whitespace and comments, counts lines for error messages, and may expand macros in some languages.
Why a separate lexical analyzer?
- Simplicity: the parser never deals with blanks and comments.
- Efficiency: reading characters is the slowest part of compiling; a specialised lexer reads input in large blocks using buffers.
- Portability: character-set quirks stay inside the lexer.
Input buffering (brief): the lexer keeps two halves of a buffer and two pointers, lexemeBegin and forward; a special end-of-buffer character (a sentinel) avoids testing for the buffer end on every character.
Story → compiler term
| In the story | In the compiler |
|---|---|
| the exact letters Mira cut out, e.g. Ramesh | lexeme |
| the stamp NAME | token name |
| the page number written on the stamp | attribute (pointer to symbol table entry) |
| AMOUNT, 50 | token ⟨num, 50⟩ with the value as attribute |
| a pattern card | pattern (regular expression) |
| Kabir ringing “next word, please” | parser calling getNextToken() |
| skipping spaces and margin notes | removing whitespace and comments |
| counting lines for complaints | tracking line numbers for error messages |
4 · Visual
The parser pulls tokens one at a time; both read and write the symbol table.
The 10 tokens of if (count >= 10) count = 0;. Colours: purple keyword, blue identifier, orange number, red operator, grey punctuation.
| Lexeme | Token name | Attribute value |
|---|---|---|
if | if | — |
( | ( | — |
count | id | pointer to entry “count” |
>= | relop | GE |
10 | num | 10 |
) | ) | — |
count | id | same pointer |
= | assign | — |
0 | num | 0 |
; | ; | — |
5 · Worked Examples
Example 1 Easy
List lexeme, token name and attribute for if (count >= 10) count = 0;.
Solution
See the table above: 10 tokens. Note the two tokens for count: Mira stamps every appearance of Ramesh, but both stamps point to the same Index Book page.
Example 2 Medium
Give the token sequence with attributes for x = y + 3.14;, assuming x is entry 1 and y is entry 2 of the symbol table.
Solution
⟨id, 1⟩ ⟨assign⟩ ⟨id, 2⟩ ⟨+⟩ ⟨num, 3.14⟩ ⟨;⟩: 6 tokens. The number’s attribute is its value; the identifiers’ attributes are symbol table pointers.
Example 3 GATE
Which of these are jobs of the lexical analyzer? (i) removing comments; (ii) checking that parentheses are balanced; (iii) entering identifiers into the symbol table; (iv) keeping line numbers for error messages; (v) checking that a variable was declared before use.
Solution
(i), (iii) and (iv) are lexer jobs. (ii) needs the arrangement of many tokens: the parser. (v) needs declarations: the semantic analyzer. Mira cuts and stamps words; she does not judge sentences or meaning.
6 · Shortcuts
⚡
Lexeme = the text, token = the kind (+ attribute), pattern = the rule. When an option says “identifier” about count, it means the token name; count itself is the lexeme.
Valid when: MCQs that test the three terms.
⚡
Lexer jobs: cut lexemes, return tokens, strip blanks and comments, fill the symbol table, count lines. Anything about the arrangement of tokens is not a lexer job. Valid when: MSQs listing candidate jobs.
7 · GATE Traps
⚠️
mainandprintfare identifiers in C, not keywords.- Every occurrence of a name is a separate token, even though all point to one symbol table entry.
- A string literal is a single token, quotes included, whatever it contains.
- The lexer does not check brackets, declarations or types.
- Comments and whitespace produce no tokens, but whitespace still separates lexemes (
int xvsintx).
8 · Memory Hook
🧠
Lexeme is what you see, token is what it is, pattern is how you know.
9 · Connect the Dots
You can now say exactly what a token is. GATE asks you to count them in real C code, where operators like ++ and >=, comments and quoted text make counting tricky. That is the next lesson.
10 · Self-Test
GATE format. Try every question before opening the vault.
Q1MCQ1 markLexeme vs token
In sum = sum + 1;, the character sequence sum is:
- (A) a token name
- (B) a lexeme
- (C) a pattern
- (D) an attribute
Q2MSQ1 markLexer jobs
Which tasks does a lexical analyzer perform?
- (A) remove comments and whitespace
- (B) enter identifiers into the symbol table
- (C) check that every
{has a matching} - (D) report an illegal character
Q3NAT1 markTokens
How many tokens does x = y + 3.14; contain?
Numerical answer: ________
Q4MCQ1 markAttributes
The attribute value of an identifier token is usually:
- (A) the identifier’s length
- (B) a pointer to its symbol table entry
- (C) the line number only
- (D) nothing; identifiers carry no attribute
Q5MCQ1 markInteraction
How does the parser usually obtain tokens?
- (A) It reads characters itself.
- (B) It calls the lexical analyzer each time it needs the next token.
- (C) It receives all tokens only after the semantic analyzer finishes.
- (D) It reads them from the code generator.
11 · Rule Card
- Token = ⟨token name, attribute⟩; lexeme = matched characters; pattern = rule (regular expression).
- Token classes: keywords, identifiers, constants, string literals, operators, punctuation.
- Attributes: id → symbol table pointer; num → value; relop → which operator.
- Parser calls getNextToken(); lexer strips blanks/comments, fills symbol table, counts lines.
- Each occurrence = one token; main/printf are identifiers.
12 · Concept Ledger
lexemetoken nameattribute valuepatternkeywordidentifierconstantstring literaloperatorpunctuationgetNextToken()input buffer / sentinel
13 · Answer Vault
Answer Vault
Try the questions first. Open when you are ready to check.
Warm-up
- R A C B: the node first, then its children left to right.
- All non-empty strings of digits; ε is not included (that would need [0-9]*).
- A compiler translates the whole program into a target program before running; an interpreter executes the source directly, statement by statement, with no target program.
Predict First
Two tokens, one for each appearance. Both have the same token name (id) and the same attribute (a pointer to the single symbol table entry for count). The whole statement has 10 tokens.
Self-Test
Q1 Answer: (B)1 mark
The actual characters in the source form a lexeme; its token name is id.
- (A) is wrong: The token name is id.
- (C) is wrong: The pattern is the rule letter(letter|digit)*.
- (D) is wrong: The attribute is the symbol table pointer.
Re-read: Lesson 1.1.1 — Tokens, lexemes, patterns and attributes; how the lexer works with the parser and symbol table
Q2 Answer: (A) (B) (D)1 mark
Matching braces depends on the arrangement of many tokens, which is the parser’s job.
Re-read: Lesson 1.1.1 — Tokens, lexemes, patterns and attributes; how the lexer works with the parser and symbol table
Q3 Answer: 61 mark
x · = · y · + · 3.14 · ; = 6.
Re-read: Lesson 1.1.1 — Tokens, lexemes, patterns and attributes; how the lexer works with the parser and symbol table
Q4 Answer: (B)1 mark
The symbol table entry holds the lexeme, type, location and more.
- (A) is wrong: Length alone is not enough to distinguish names.
- (C) is wrong: Line numbers are kept separately for errors.
- (D) is wrong: Without an attribute, two different names would look the same.
Re-read: Lesson 1.1.1 — Tokens, lexemes, patterns and attributes; how the lexer works with the parser and symbol table
Q5 Answer: (B)1 mark
The lexer works on demand as a subroutine of the parser (getNextToken).
- (A) is wrong: Reading characters is the lexer’s job.
- (C) is wrong: The semantic analyzer comes after the parser.
- (D) is wrong: The code generator is at the other end of the compiler.
Re-read: Lesson 1.1.1 — Tokens, lexemes, patterns and attributes; how the lexer works with the parser and symbol table